Postgresql - Patroni 3 Node High Availability Overview
Document 1: Architecture Overview
PostgreSQL High Availability with Patroni
Overview
A three-node PostgreSQL 16 cluster managed by Patroni, using the Raft consensus algorithm for leader election. The cluster runs across a hybrid infrastructure of one always-on TrueNAS node and two Proxmox virtual machines, orchestrated by Docker Swarm. HAProxy provides transparent connection routing to the current primary, and keepalived floats a virtual IP across all database nodes for client access.
Architecture Diagram
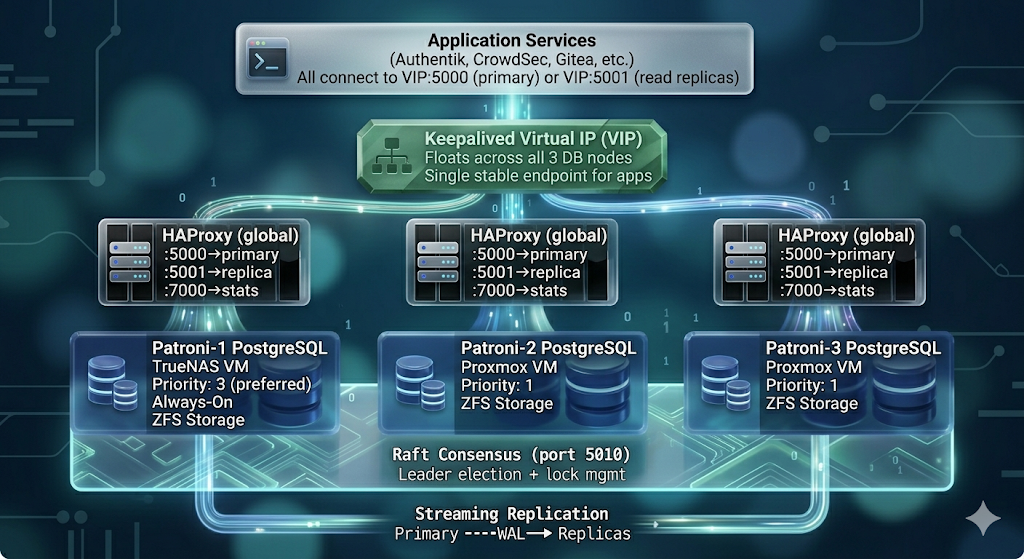
                    ┌──────────────────────────────────────┐
                    │         Application Services          │
                    │   (Authentik, CrowdSec, Gitea, etc.)  │
                    │                                      │
                    │   All connect to VIP:5000 (primary)   │
                    │   or VIP:5001 (read replicas)         │
                    └────────────────┬─────────────────────┘
                                     │
                    ┌────────────────▼─────────────────────┐
                    │     Keepalived Virtual IP (VIP)       │
                    │     Floats across all 3 DB nodes      │
                    │     Single stable endpoint for apps   │
                    └──┬─────────────┬─────────────┬───────┘
                       │             │             │
          ┌────────────▼──┐  ┌──────▼───────┐  ┌──▼────────────┐
          │   HAProxy     │  │   HAProxy    │  │   HAProxy     │
          │   (global)    │  │   (global)   │  │   (global)    │
          │               │  │              │  │               │
          │ :5000→primary │  │ :5000→primary│  │ :5000→primary │
          │ :5001→replica │  │ :5001→replica│  │ :5001→replica │
          │ :7000→stats   │  │ :7000→stats  │  │ :7000→stats   │
          └──────┬────────┘  └──────┬───────┘  └───────┬───────┘
                 │                  │                   │
          ┌──────▼────────┐  ┌──────▼───────┐  ┌───────▼───────┐
          │  Patroni-1    │  │  Patroni-2   │  │  Patroni-3    │
          │  PostgreSQL   │  │  PostgreSQL  │  │  PostgreSQL   │
          │               │  │              │  │               │
          │  TrueNAS VM   │  │  Proxmox VM  │  │  Proxmox VM  │
          │  Priority: 3  │  │  Priority: 1 │  │  Priority: 1  │
          │  (preferred)  │  │              │  │               │
          │  Always-On    │  │              │  │               │
          └──────┬────────┘  └──────┬───────┘  └───────┬───────┘
                 │                  │                   │
                 │    Raft Consensus (port 5010)        │
                 │    Leader election + lock mgmt       │
                 └──────────────────┼───────────────────┘
                                    │
                         Streaming Replication
                       Primary ──WAL──▶ Replicas
Components
PostgreSQL 16
The relational database engine. One instance runs as the primary (accepts reads and writes), the others run as replicas (read-only, streaming replication from the primary).
Patroni
A cluster manager that runs alongside each PostgreSQL instance. It handles:
- Bootstrap — initializing the cluster and creating replicas via
pg_basebackup - Leader election — using Internal Raft consensus to decide which node is the primary, you can use external leader locks like
etcd - Automatic failover — detecting primary failure and promoting a replica
- Replica management — configuring replication, handling rejoins with
pg_rewind - REST API — exposing cluster health on port 8008 for HAProxy load balancer health checks
Raft Consensus
The distributed consensus algorithm used for leader election. Patroni nodes communicate on port 5010 to maintain agreement on who holds the leader lock. Requires a quorum (majority) of nodes to make decisions.
3 nodes → quorum = 2 → can lose 1 node and still elect a leader
HAProxy
A TCP load balancer that routes database connections. It queries each Patroni node's REST API to determine the current cluster topology:
GET /primaryreturns200only on the current primaryGET /replicareturns200only on healthy replicas- All other nodes return
503
HAProxy runs on every database node, so any node can serve as an entry point.
Keepalived
Provides a floating Virtual IP (VIP) that automatically moves between database nodes. Applications connect to the VIP and are transparently routed to a healthy HAProxy instance, which in turn routes to the correct PostgreSQL primary or READ only replica.
How Failover Works
Timeline of an automatic failover:

t=0s     Primary node crashes or becomes unreachable
t=9s     HAProxy detects failure (3 checks × 3s interval)
         Existing connections to old primary are terminated (RST)
t=10s    Patroni loop_wait expires on surviving nodes
t=30s    Raft TTL expires, leader lock becomes available
         Surviving nodes compete for the lock
         Highest priority node with least replication lag wins
         Winner runs: pg_ctl promote
t=33s    HAProxy detects new primary (returns 200 on /primary)
         New connections route to promoted node
t=35s    Service restored — total outage ~30-35 seconds

Later    Old primary comes back online
         Patroni runs pg_rewind to sync diverged timeline
         Old primary rejoins as a replica automatically
Failover Priority
The TrueNAS node has a higher failover priority (3 vs 1), making it the preferred promotion target. During a tiebreak where multiple replicas have identical replication lag, the TrueNAS node wins. This ensures the primary gravitates toward the always-on infrastructure.
Important: Priority is secondary to data integrity. A replica with more up-to-date data always wins, regardless of priority.
Quorum and Power Management
Nodes alive    Quorum?    Auto-failover?    Writes?
3              ✓          ✓                 ✓
2              ✓          ✓                 ✓
1              ✗          ✗                 ✗ (demoted)
With only one node alive, Raft cannot form quorum. Patroni demotes the remaining primary to prevent split-brain. To safely shut down multiple nodes:
1. Switchover primary to chosen node
2. Pause Patroni (freezes cluster management)
3. Shut down Proxmox nodes freely
4. PostgreSQL stays writable on chosen node
5. Resume Patroni when nodes return
Backup Strategy
Three independent VM's across three separate physical Proxmox hosts, each with automated backup schedules:
- 2 hourly snapshots sent to external ProxmoxBackupServer (PBS).
Connection Flow
Application (e.g., Nextcloud)
    │
    │  postgres://user:pass@VIP:5000/dbname
    │
    ▼
Keepalived VIP
    │
    │  Floats to healthiest DB node
    │
    ▼
HAProxy (on whichever node holds the VIP)
    │
    │  HTTP health check: GET /primary → 200?
    │  Routes TCP to the node that responds 200
    │
    ▼
Patroni/PostgreSQL (current primary)
    │
    │  Streams WAL to replicas
    │
    ├──▶ Replica 1 (read-only)
    └──▶ Replica 2 (read-only)
Applications connect to a single stable endpoint. They never need to know which node is the primary. Failover is completely transparent — the application sees a brief connection drop (~30s) and reconnects to the new primary automatically.
Network Topology
Physical Network (LAN)
│
├── TrueNAS Server
│   └── VM: db-node-1 (NixOS, Docker Swarm worker)
│       ├── Patroni + PostgreSQL (priority 3)
│       ├── HAProxy (global)
│       └── Keepalived (highest priority)
│
├── Proxmox Node A
│   └── VM: db-node-2 (NixOS, Docker Swarm worker)
│       ├── Patroni + PostgreSQL (priority 1)
│       ├── HAProxy (global)
│       └── Keepalived
│
├── Proxmox Node B
│   └── VM: db-node-3 (NixOS, Docker Swarm worker)
│       ├── Patroni + PostgreSQL (priority 1)
│       ├── HAProxy (global)
│       └── Keepalived
│
├── Existing Swarm Cluster (Proxmox VMs)
│   ├── traefik, authentik, crowdsec, etc.
│   └── Connect to DB via VIP:5000
│
└── Virtual IP (floats between db-node-1/2/3)
    └── Single entry point for all database traffic
Port Map
| Port | Service | Protocol | Purpose |
|---|---|---|---|
| 5432 | PostgreSQL | TCP | Direct database connections |
| 5010 | Patroni Raft | TCP | Consensus communication between nodes |
| 8008 | Patroni REST API | HTTP | Health checks, cluster status |
| 5000 | HAProxy | TCP | Routed connection to current primary |
| 5001 | HAProxy | TCP | Routed connections to replicas (round-robin) |
| 7000 | HAProxy Stats | HTTP | Dashboard showing backend health |